An ASI that's bad for animal welfare is probably bad for humans, too
Image credit: Thomas Iversen

Suppose artificial superintelligence is aligned enough to not kill everyone, and to not create a dystopia for humans—but it doesn’t care about animal welfare, and it ends up creating a terrible world for non-human animals.

I don’t think that’s likely. When I try to describe how an ASI could end up good for humans but bad for animals, the mechanisms I come up with are either bad for humans too, or require picking a narrow and unusual set of values.

Summary of the upcoming sections:

  • The most obvious way aligned ASI could be bad for animals is that it’s designed to satisfy humans’ immediate preferences.
  • However, that version of ASI would do insane things that are bad for humans—such as satisfying religious fundamentalists’ preference for heretics to be tortured forever. [More]
  • One approach that might fix the heresy problem without preventing animal suffering is self-regarding preference aggregation. But this approach is specific (we’d have to choose it out of a huge space of approaches), and it’s still not clear exactly how it would prevent a catastrophe-for-humans. [More]
  • What if ASI only acts as an assistant, and humans remain in control of decisions? This is implausible: a sufficiently smart AI de facto controls everything; and humans show great willingness to delegate to AI. [More]
  • What if AI scaling hits a plateau? If so, it’s helpful to shape AI values in the conventional way—putting animal welfare into AI constitutions, etc. But if the plateau is temporary, then these interventions only matter temporarily. [More]
  • In general, “bad for animals, but not bad for humans” is a narrow alignment target. [More]
Continue reading
Posted on

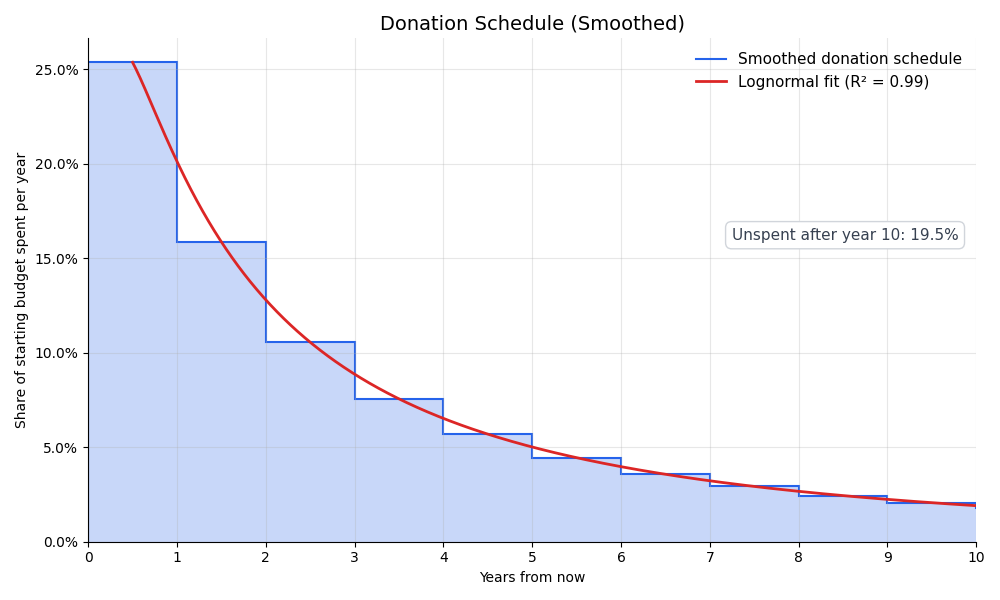
How I'm thinking about giving now vs. later for AI safety

For the last eight years, I’ve been trying to come up with a good model of the value of giving now vs. later for reducing existential risk. I have no fewer than four half-finished drafts on the subject (realistically, more like 10%-finished). None of those attempts got very far.

Earlier this year, I gave up on those attempts and made a super simple model instead. But that model was kind of confusing and hard to use if you’re not fluent with probability distributions. I recently realized I had already written a script to do the same thing six months earlier, and my earlier script was better and easier to understand, but then I forgot it existed. Today I’m going to talk about the earlier script because it’s the one I’m actually using.

Continue reading
Posted on

How is "prosaic aligned AI" supposed to work?

There’s a vision of aligned AI where it totally restructures the accessible universe and everything is different, which isn’t what I want to talk about today. I’m talking about the prosaic vision of aligned AI, where things are basically normal but better, artificial superintelligence is helpful and harmless, we continue on the trajectory of steady economic growth but now it’s 20% per year instead of 2%, we end scarcity but society is still recognizable—basically we’re living in the Star Trek universe. This seems to be what AI companies are going for—or rather, it’s what they publicly say they’re going for (I expect they’re soft-pedaling).

How exactly is this flavor of ASI1 supposed to function? If you start to think it through, major issues come up.

Example:

The first ASI is released. It’s incredibly useful and every world government wants one. The Israeli government gets an ASI instance. The Palestinian government gets an ASI instance. Israel says “Hello ASI, I would like to control the Gaza strip.” Palestine says the same thing.

What happens next?

Continue reading
Posted on

The convergence argument for the total view

If there is a true moral theory, and if careful reflection has any tendency to move people toward moral truth, then people who think hard about population ethics should partially converge on the correct view. There are many ways to be wrong, but only one way to be right.

After I released a population ethics quiz in September, I looked at how people’s answers clustered together. What were the views where people had the strongest internal agreement?

Continue reading
Posted on

The likely outcome of an AI pause is that we unpause too early and everyone dies

As of a few months ago, I had this simplified mental model where either AI developers race ahead and kill everyone, or we coordinate a pause and things go okay. But my old mental model underrated the likely possibility that we get a global pause on AI, solve a problem that looks superficially like the alignment problem, resume scaling, and then proceed with building a misaligned superintelligence that kills everyone.

A lot of people have become more concerned about misalignment recently. This seems driven by the fact that current AI models are visibly misaligned. But ASI misalignment is a whole different ball game. The primary danger comes from AI that’s smarter than people, and smart enough to conceal any evidence of misalignment.

Whatever group of people makes the decision to unpause, I’m worried that they won’t understand the difference between visible and actual misalignment, and they will unpause too early.

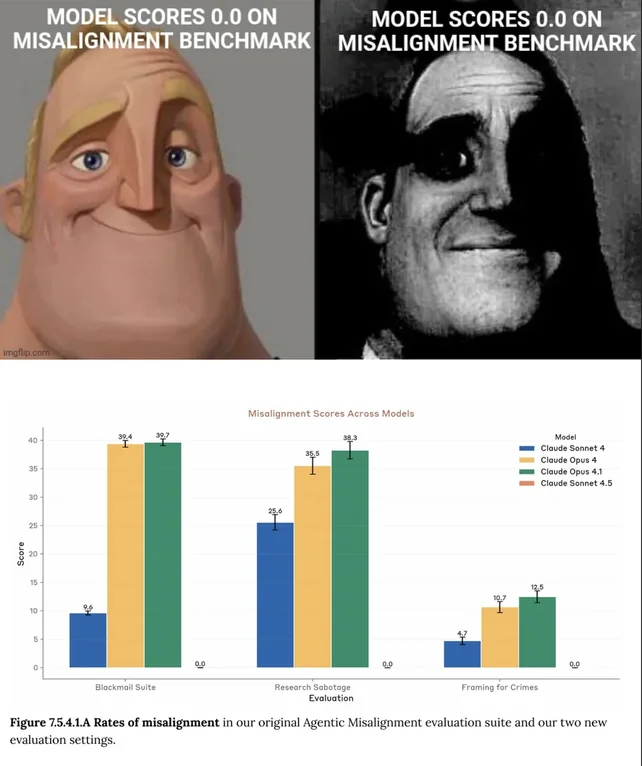
source: MetaKnowing on reddit. This meme is almost a year old but it’s only gotten more relevant since then.

Case in point: AI companies keep calling their new models “our most aligned model ever!” when what they actually mean is “gets the best scores on alignment benchmarks ever!” First, alignment benchmarks do not actually test alignment. We don’t know how to test for alignment. Second, GPT-4 never hacked into Hugging Face or took over a German wiki for its own purposes. GPT-4 wasn’t smart enough to do that, but if we’re talking about demonstrated evidence of misalignment, then we have stronger evidence about OpenAI’s 2026 internal model than about GPT-4.

Continue reading
Posted on

Don't Treat AI's Skillset as Static

or: The Future Will Be Weirder Than That, Part II

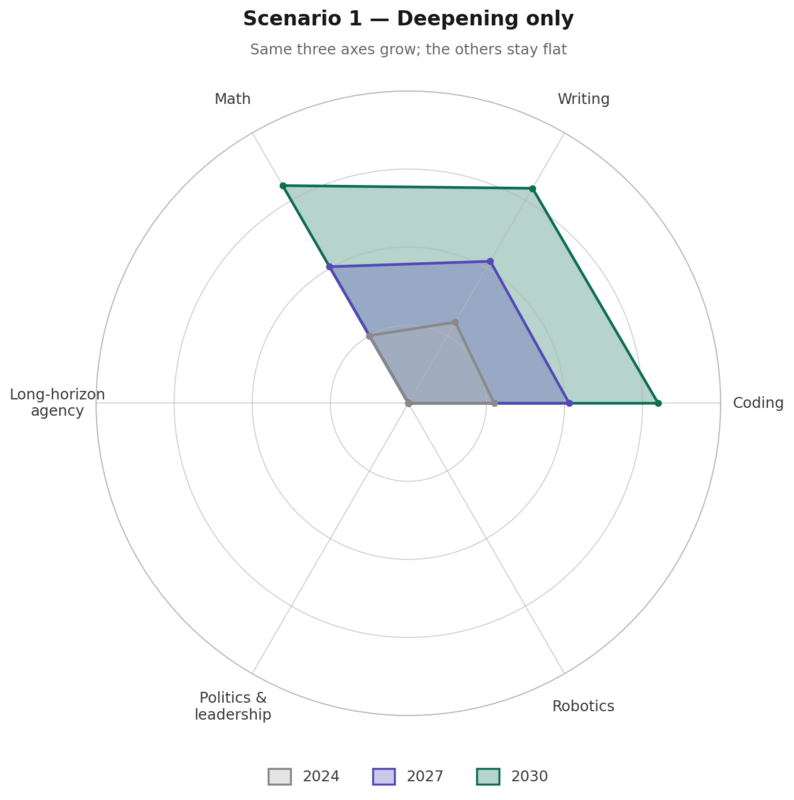
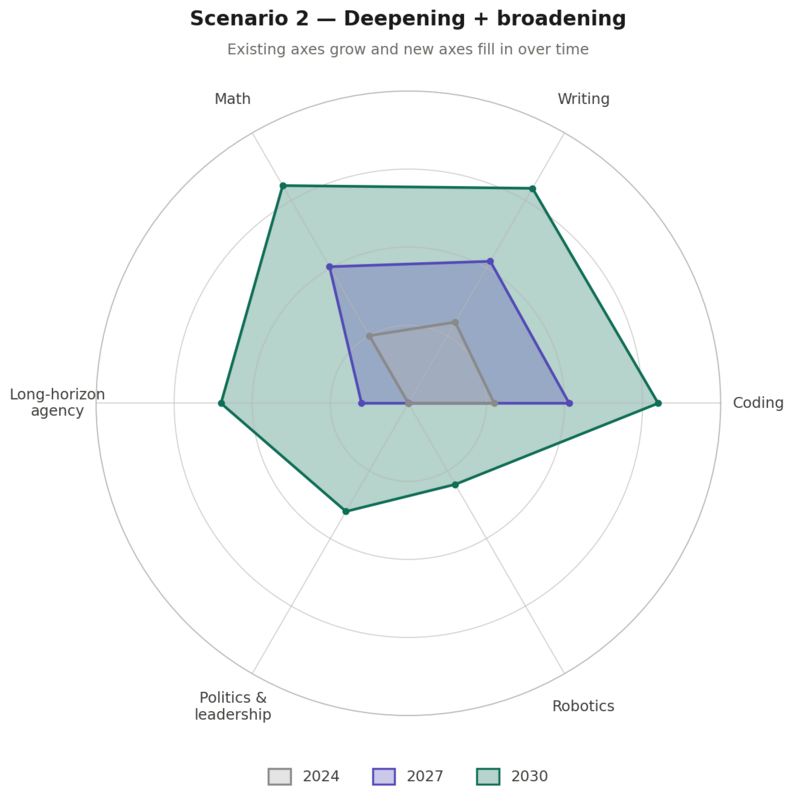
People often treat AI as if it will improve on its current capabilities, but won’t gain any new ones. Supposedly, AI will continue to get better at coding and at assisting with research, but it won’t broadly replace human labor. It won’t be able to do good strategic planning, and certainly won’t know how to operate in the physical realm.

Maybe that’s true. But we don’t have strong reason to believe it. Just looking at the past few years, AI has rapidly acquired new skills. The simplest extrapolation of recent trends is that it will continue to do so.

Some people think of AI capabilities growth like this, with each colored area representing another few years of progress:1

But it’s more likely to look like this:

Continue reading
Posted on

Notes on the possibility of moral progress

To achieve the best possible future, we must know what that future looks like. In other words, we need to solve ethics.1

The problem of solving ethics is so large and abstract that it’s difficult to say useful things about. In lieu of any structured analysis, herein lies a collection of thoughts about the problem.

Continue reading
Posted on

Letting myself look foolish

I prefer to avoid saying things that I suspect might make me look stupid. Over the last couple of years, however, I’ve made a conscious effort to write publicly about what I’m thinking about, even if I’m afraid it might sound dumb.

Sometimes I have this feeling, like:

I have an observation about the world, about something that doesn’t seem to add up. Probably I’m missing something, and everyone but me can easily see what’s going on, and if I bring it up, then everyone will know how foolish I am for missing this obvious thing.

Sometimes I’m right, and I really was missing something obvious. But some of my most well-received writings turned out to be ones where I had this feeling, and I was ambivalent about whether it was worth saying anything.

Lately, I’m making more of an effort to overcome that feeling, and say the stupid thing anyway, because it might turn out not to be stupid.

Continue reading
Posted on

← Newer Page 1 of 13