An ASI that's bad for animal welfare is probably bad for humans, too
Image credit: Thomas Iversen

Suppose artificial superintelligence is aligned enough to not kill everyone, and to not create a dystopia for humans—but it doesn’t care about animal welfare, and it ends up creating a terrible world for non-human animals.

I don’t think that’s likely. When I try to describe how an ASI could end up good for humans but bad for animals, the mechanisms I come up with are either bad for humans too, or require picking a narrow and unusual set of values.

Summary of the upcoming sections:

  • The most obvious way aligned ASI could be bad for animals is that it’s designed to satisfy humans’ immediate preferences.
  • However, that version of ASI would do insane things that are bad for humans—such as satisfying religious fundamentalists’ preference for heretics to be tortured forever. [More]
  • One approach that might fix the heresy problem without preventing animal suffering is self-regarding preference aggregation. But this approach is specific (we’d have to choose it out of a huge space of approaches), and it’s still not clear exactly how it would prevent a catastrophe-for-humans. [More]
  • What if ASI only acts as an assistant, and humans remain in control of decisions? This is implausible: a sufficiently smart AI de facto controls everything; and humans show great willingness to delegate to AI. [More]
  • What if AI scaling hits a plateau? If so, it’s helpful to shape AI values in the conventional way—putting animal welfare into AI constitutions, etc. But if the plateau is temporary, then these interventions only matter temporarily. [More]
  • In general, “bad for animals, but not bad for humans” is a narrow alignment target. [More]
Continue reading
Posted on

How I'm thinking about giving now vs. later for AI safety

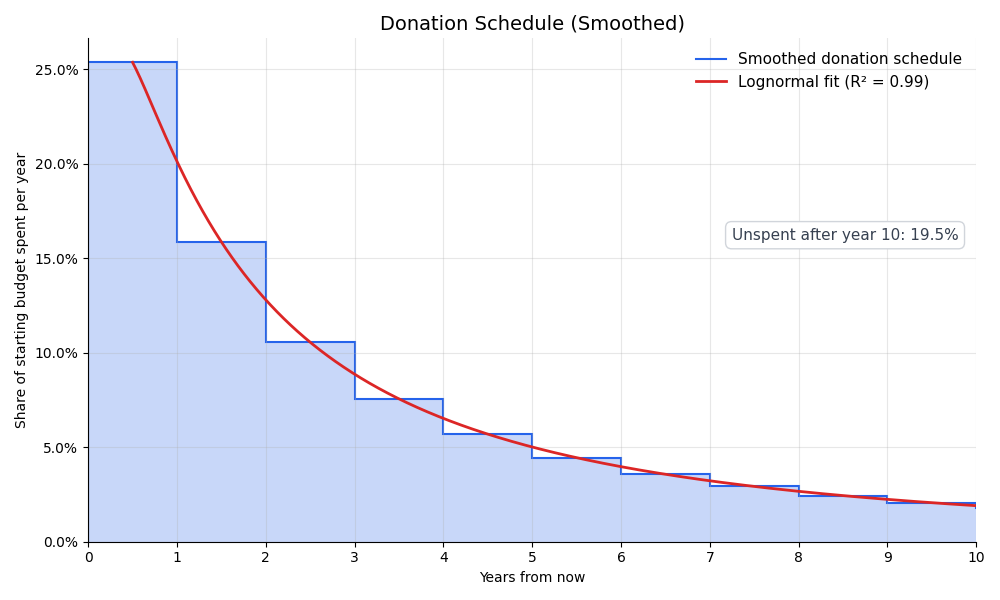
For the last eight years, I’ve been trying to come up with a good model of the value of giving now vs. later for reducing existential risk. I have no fewer than four half-finished drafts on the subject (realistically, more like 10%-finished). None of those attempts got very far.

Earlier this year, I gave up on those attempts and made a super simple model instead. But that model was kind of confusing and hard to use if you’re not fluent with probability distributions. I recently realized I had already written a script to do the same thing six months earlier, and my earlier script was better and easier to understand, but then I forgot it existed. Today I’m going to talk about the earlier script because it’s the one I’m actually using.

Continue reading
Posted on

How is "prosaic aligned AI" supposed to work?

There’s a vision of aligned AI where it totally restructures the accessible universe and everything is different, which isn’t what I want to talk about today. I’m talking about the prosaic vision of aligned AI, where things are basically normal but better, artificial superintelligence is helpful and harmless, we continue on the trajectory of steady economic growth but now it’s 20% per year instead of 2%, we end scarcity but society is still recognizable—basically we’re living in the Star Trek universe. This seems to be what AI companies are going for—or rather, it’s what they publicly say they’re going for (I expect they’re soft-pedaling).

How exactly is this flavor of ASI1 supposed to function? If you start to think it through, major issues come up.

Example:

The first ASI is released. It’s incredibly useful and every world government wants one. The Israeli government gets an ASI instance. The Palestinian government gets an ASI instance. Israel says “Hello ASI, I would like to control the Gaza strip.” Palestine says the same thing.

What happens next?

Continue reading
Posted on

The convergence argument for the total view

If there is a true moral theory, and if careful reflection has any tendency to move people toward moral truth, then people who think hard about population ethics should partially converge on the correct view. There are many ways to be wrong, but only one way to be right.

After I released a population ethics quiz in September, I looked at how people’s answers clustered together. What were the views where people had the strongest internal agreement?

Continue reading
Posted on

Results from Version 2 of the Population Ethics Quiz

On the same day as I published the results from my population ethics quiz, I also introduced version 2 of the quiz. The new version adds some new questions to distinguish between types of people who accept the repugnant conclusion. It distinguishes between classical views, which treat happiness and suffering as symmetric, and negative-leaning views, which give special weight to suffering.

I’ve now gotten 192 results from new quiz-takers. Here are the findings.

Continue reading
Posted on

The likely outcome of an AI pause is that we unpause too early and everyone dies

As of a few months ago, I had this simplified mental model where either AI developers race ahead and kill everyone, or we coordinate a pause and things go okay. But my old mental model underrated the likely possibility that we get a global pause on AI, solve a problem that looks superficially like the alignment problem, resume scaling, and then proceed with building a misaligned superintelligence that kills everyone.

A lot of people have become more concerned about misalignment recently. This seems driven by the fact that current AI models are visibly misaligned. But ASI misalignment is a whole different ball game. The primary danger comes from AI that’s smarter than people, and smart enough to conceal any evidence of misalignment.

Whatever group of people makes the decision to unpause, I’m worried that they won’t understand the difference between visible and actual misalignment, and they will unpause too early.

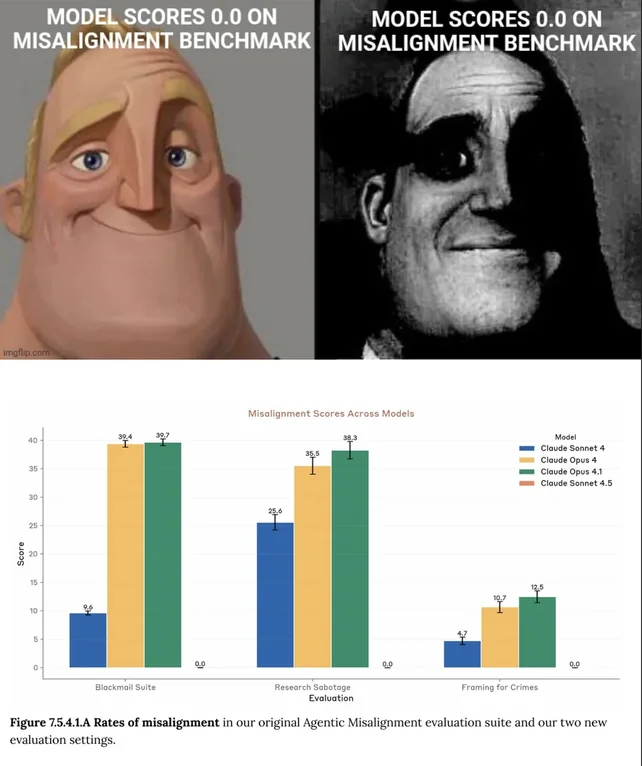
source: MetaKnowing on reddit. This meme is almost a year old but it’s only gotten more relevant since then.

Case in point: AI companies keep calling their new models “our most aligned model ever!” when what they actually mean is “gets the best scores on alignment benchmarks ever!” First, alignment benchmarks do not actually test alignment. We don’t know how to test for alignment. Second, GPT-4 never hacked into Hugging Face or took over a German wiki for its own purposes. GPT-4 wasn’t smart enough to do that, but if we’re talking about demonstrated evidence of misalignment, then we have stronger evidence about OpenAI’s 2026 internal model than about GPT-4.

Continue reading
Posted on

Campaign spending limits would reduce extinction risk (but spending limits might not accord with Constitutional principles)

Many people support stricter regulations on frontier AI, and some of those people donate to political campaigns for pro-regulation candidates. Not many people oppose AI regulations, but that group includes AI companies and execs who have giant piles of cash to throw at super PACs.

This situation is made possible by three court decisions:

  1. Buckley v. Valeo (1976) held that limits on independent political spending violate the First Amendment (while limits on direct contributions to candidates do not).
  2. Citizens United (2010) extended those First Amendment protections to corporations and unions, thus allowing them to spend unlimited money on political ads.
  3. SpeechNow.org v. FEC (2010) built on Citizens United to allow unlimited donations to independent-expenditure-only committees—i.e., super PACs—as long as they don’t directly work with political candidates.

Donations straight to a candidate are still capped at a few thousand dollars per person; donations to a super PAC supporting that candidate are not. If SpeechNow were overturned, or a law passed overriding it, the $5,000 cap on super PAC contributions would apply again, which means the popularity of a position would matter more than how rich its supporters are.

(I often hear “Overturn Citizens United” as the slogan, but SpeechNow allows super PACs to exist, and Buckley v. Valeo enables unlimited spending by individuals. What the advocacy groups in the space really want to do is restore the power of Congress and the states to enforce spending limits.)

Restoring spending limits would prevent unpopular but rich anti-regulation special interests (like Leading the Future) from dominating the political funding landscape. This would make the AI regulation situation better, but it would also improve the situation on any policy issues where unpopular, wealthy special interests wield disproportionate (and arguably un-democratic) influence.

It would also worsen any situation in which rich special interests are in the right, and the majority is in the wrong. But there aren’t many of those, and anyway there’s good reason to dislike an un-democratic process even if it produces a good outcome in a particular case.

An important caveat: Before writing this post, I was confident that imposing campaign spending limits would be a good thing. After doing some more research, I find it hard to dismiss the free speech defense of unlimited campaign spending (I’ll say more about this in the next section). Both sides of the debate have points in their favor. My thesis in this post should be taken as the narrow claim that campaign spending limits would have positive first-order effects on AI extinction risk, and they’re worth exploring on that basis. I don’t have an established view on whether stricter spending limits would be good or bad all-things-considered.

Continue reading
Posted on

Population ethics is a big deal, which is why I made this population ethics quiz

TLDR: Take the population ethics quiz here: https://mdickens.me/pop-ethics/

Population ethics is an oft-overlooked subfield within ethics. Many people hold views that they don’t realize contradict each other, or that have strange implications that they wouldn’t endorse if they thought about it more.

Not just that—population ethics is a BIG DEAL. A lot of ethical decisions hinge on how you think about changes in future populations.

I’ll give concrete examples below the fold, but reading the examples might change your answers, so you should take the quiz first. It has 13 to 17 short questions. (Questions are skipped when they can’t affect the results.)

Continue reading
Posted on

← Newer Page 1 of 24